PDF tables to JSON
An account and payment are required for PDF-to-JPG, all other converters and Premium tools. No free Premium jobs.
Compare free and paid accessExtract PDF tables as JSON with AlphaPDF Premium. Review detected rows before importing the result.
Export PDF tables as structured JSON with a tables collection for downstream processing. This flow extracts table data rather than a full-page OCR transcript.
An empty collection means no tables were detected. Validate the extracted rows before importing them; use OCR JSON for page text and recognition blocks.
Sign in to start
Premium processing keeps every input and result scoped to your own account.
Log inNew to AlphaPDF? Create an account
What it does
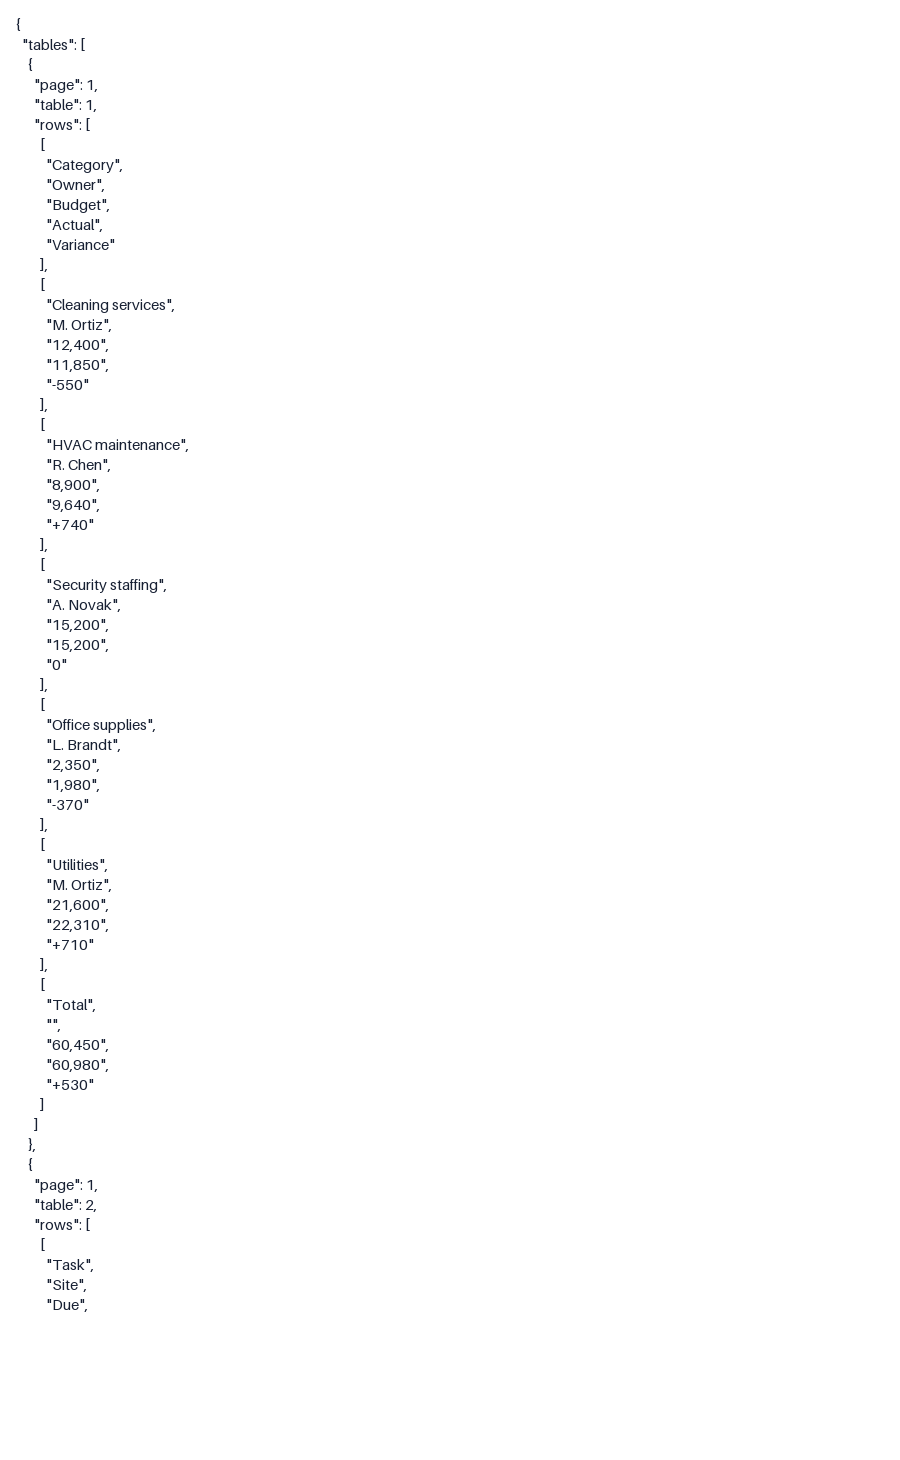
PDF tables to JSON writes every table it finds into one JSON file with a tables collection. Each table lists its rows and cells in order, which makes it simple to read from code.
When to use it
Use it when a developer or an automated workflow needs table data from PDFs, for example to import supplier price lists or check reports on a schedule.
How to use PDF tables to JSON
- Sign in with an account that has Premium access.
- Upload .pdf files. Each file can be up to 50 MB, with up to 25 files per batch.
- The output is set to JSON. Review the available settings and choose a 1, 7 or 30-day retention period, or Delete now to keep the result for just an hour.
- Start the job, then download and check the result before its retention period ends.
Related conversion options
Before you start
An empty collection means no tables were detected. Validate the extracted rows before importing them; use OCR JSON for page text and recognition blocks.
This extracts tables only. For all the text on a page, including paragraphs, use one of the OCR JSON tools.
Processing limits
Up to 50 MB per input; 25 files and 500 MB per batch. PDF limit: 2000 pages. Up to 2 active jobs per account. Output limit: 1000 MB. Renderer limits can reject especially large pages or images.
Example result
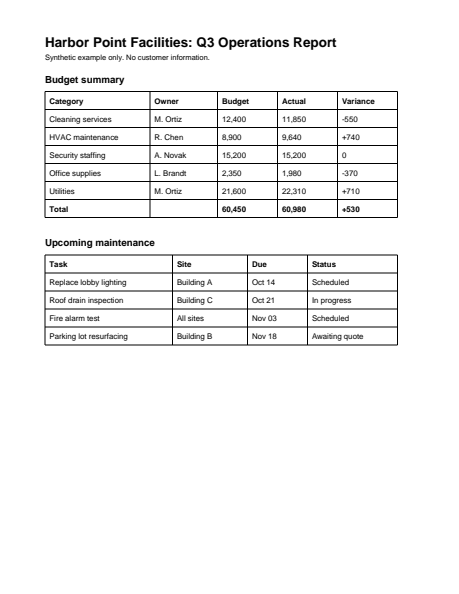
Real PDF tables to JSON output from a synthetic input. Text view of the actual output file, not a layout capture.
Download example input · Download result
Example details & evidence
Real PDF tables to JSON output from a synthetic input. Text view of the actual output file, not a layout capture.
Examples use synthetic files, not customer documents. Generation notes and SHA-256 hashes.
Common questions
What does an empty result mean?
The tables collection is empty when no tables were detected in the PDF.
Are numbers typed as numbers?
Cells are kept as text as they appear, so your code decides how to parse numbers and dates.
Does it include page numbers?
Tables are listed in page order. Check the JSON for the page each one came from before relying on it.
Can I run it on many PDFs?
Yes. Upload a batch and each PDF produces its own JSON file.